Affiliate disclosure: Some links on this page may be affiliate or sponsored links. We may earn a commission at no extra cost to you. This does not change our editorial criteria.
Rent NVIDIA B200 GPUs
This page is a beginner guide to the NVIDIA B200, a data-center graphics chip from NVIDIA's Blackwell generation. A GPU is a graphics processing unit: a chip that is very good at the math in AI training and inference. GPU cloud means you rent those chips by the hour, then shut them off when the work ends.
Who it is for: teams who have been told the next machines are "B200s" or "Blackwell" and need to know what they are renting. You do not need to be an ML engineer to follow this page.
Blackwell is the architecture after Hopper (the family that includes H100 and H200). B200 is the GPU. It is not automatically a whole rack. You rent B200s when you already know the job needs this generation, a provider actually has them, and you can still turn the meter off. If the plan is a floor of Blackwell that never goes dark, you are shopping for power and a site. That is powered land.
What a B200 actually is, and what it is not
CUDA is NVIDIA's software layer for NVIDIA chips. PyTorch and NVIDIA NeMo jobs expect CUDA drivers. What is new is the generation: NVIDIA's Blackwell pages describe a second-generation Transformer Engine (extra hardware for language-model math) and support for FP4, a 4-bit number format. Smaller numbers can mean the model takes less memory and the chip does more math per second, with some accuracy tradeoff you have to test.
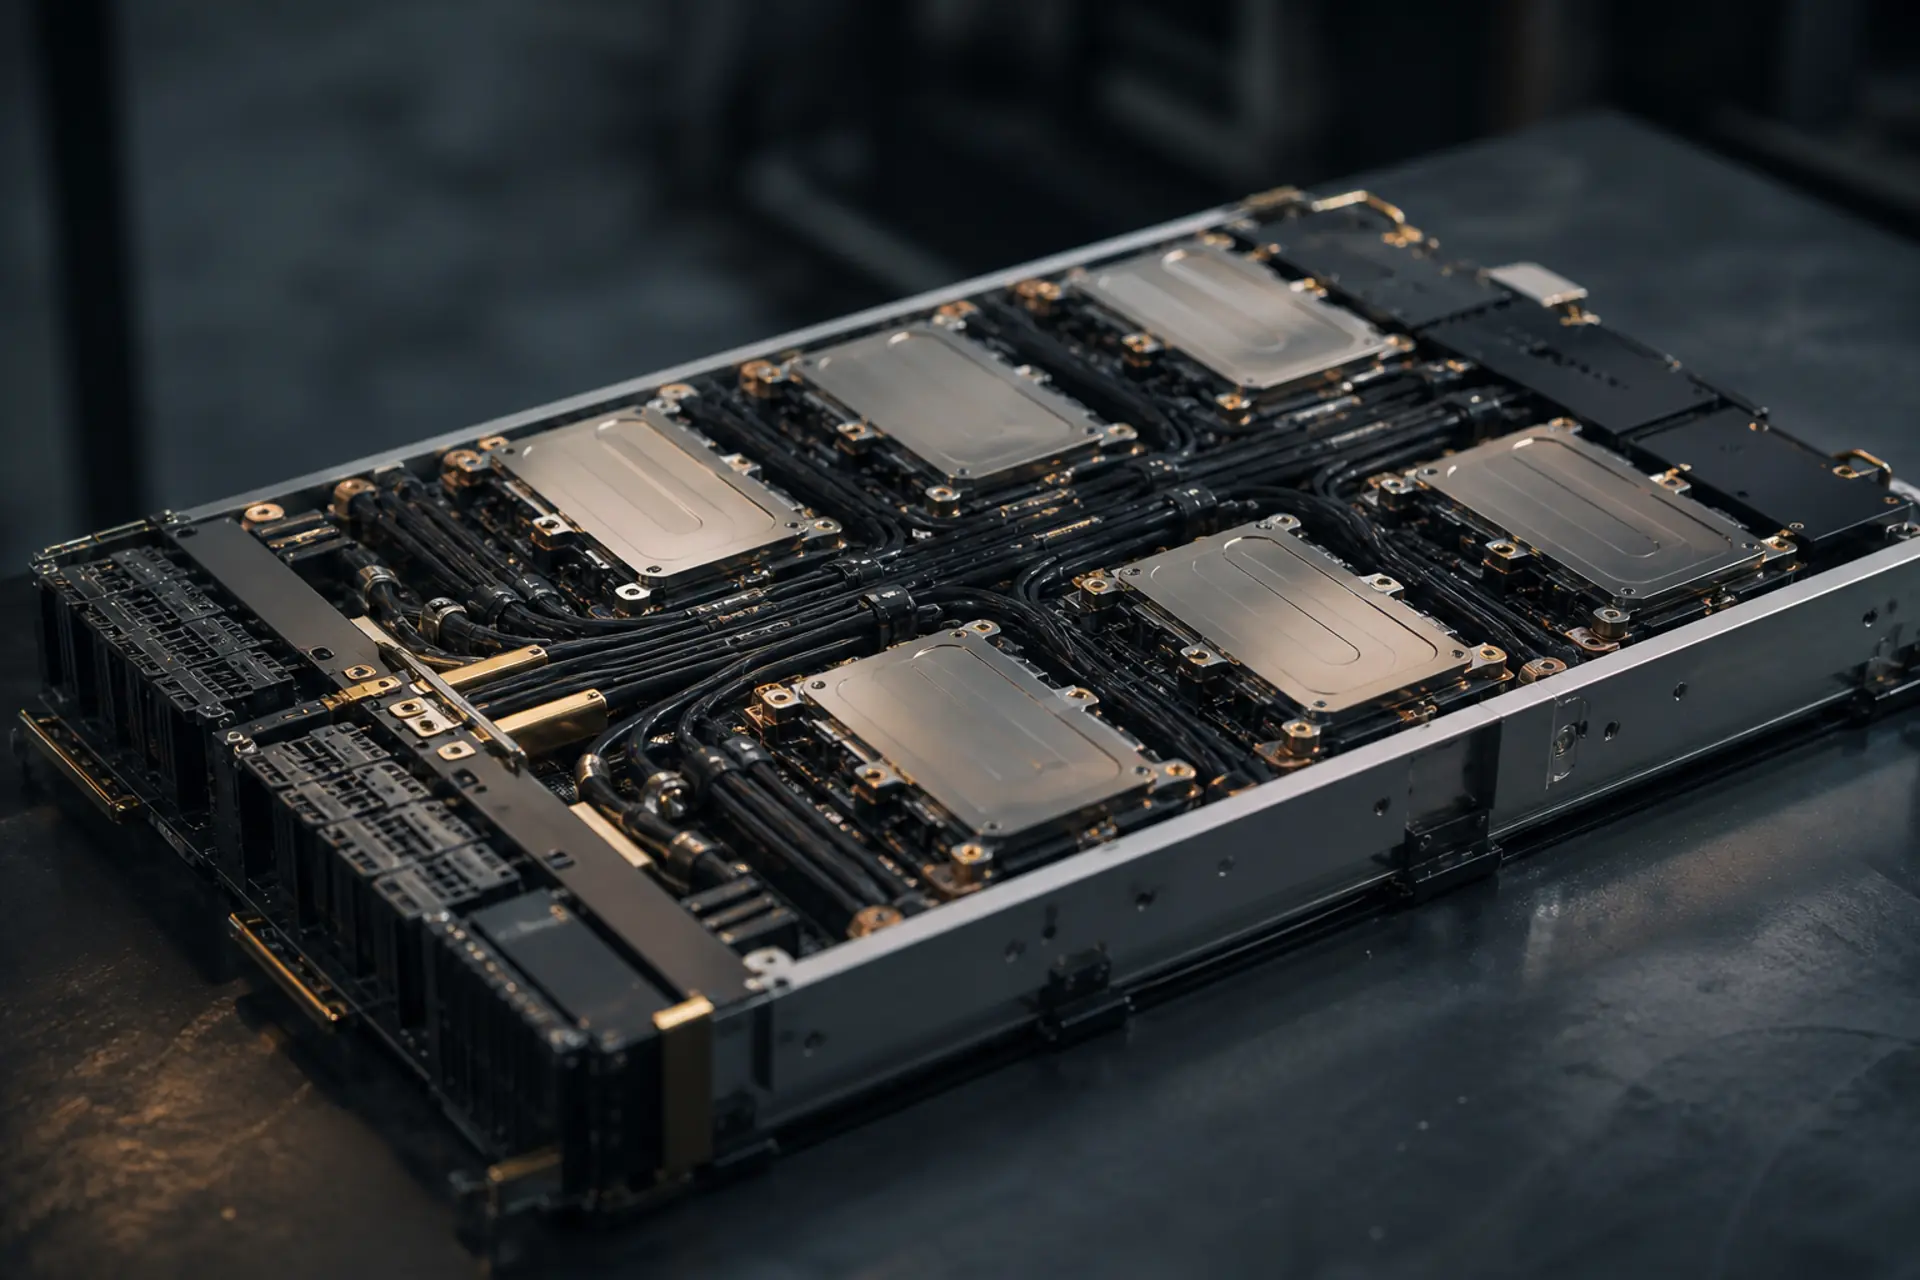
HBM is high bandwidth memory: the GPU's own fast memory. NVIDIA's DGX B200 page (a full NVIDIA server built around this generation) lists eight Blackwell GPUs with 1,440 GB of HBM3e in total and 64 TB/s of memory bandwidth across the box. That is a lot of memory in one machine. Cloud listings may say "B200," "HGX B200" (NVIDIA's multi-GPU server board), or "DGX B200" (NVIDIA's full branded server). Those are not identical products. Ask how many GPUs, how much memory per GPU, and how the GPUs connect.
NVLink is NVIDIA's fast link between GPUs. Blackwell uses a newer generation of NVLink than Hopper. Fifth-generation NVLink is why eight B200s in one server can train together without crawling through ordinary networking. SXM is the dense tray style. If the listing is a single PCIe card, it is a different shape than an 8-GPU training node.
B200 is not GB200. NVIDIA's GB200 NVL72 page describes a rack-scale system that pairs Grace CPUs (NVIDIA's server CPU) with Blackwell GPUs, 72 GPUs in one NVLink domain. That is a building-block for an AI factory, not an afternoon notebook. If a quote says GB200 or NVL72, you are looking at a different purchase than "one B200."
You rent B200s for large training when Hopper is the bottleneck
Training means teaching a model from lots of data. Full training of a serious language model already wanted many matching Hopper GPUs. Blackwell is the next step when the team has outgrown H100/H200 hours: bigger models, longer context, or a need to finish a run on fewer nodes.
You rent B200s for training when the software stack is ready, the provider can give you matching chips with the NVLink you think you bought, and the experiment still has a stop date. Save checkpoints (snapshots) often. Do not buy a rack because a blog said Blackwell is faster. Prove the run. The workload checklist is rent GPUs for LLM training.
Availability is the other half of the product. A B200 reservation that starts next quarter is not "capacity now." An H200 node you can start tonight may be the better rental while you wait.
You rent B200s for inference when Hopper is too small or too slow
Inference means using a trained model to write answers. NVIDIA's Blackwell materials emphasize real-time inference on very large models, FP4, and TensorRT-LLM (NVIDIA's library for running language models fast). vLLM and other open engines are still in the mix. You do not have to use NVIDIA's serving stack. You do need drivers, CUDA, and enough memory to load the model.
You rent B200s for inference when Hopper memory or throughput is the limiter, traffic is still a guess, and you can add or remove machines. If the assistant is the product and the GPUs never turn off, rental is a cash-flow choice. See GPU rental for LLM inference. Fine-tunes can also land here, but many LoRA-style jobs (training a small extra set of weights) still fit on H100 or H200. Do not rent Blackwell to look modern.
Simulation and render are not why most teams rent B200
Scientific CUDA codes can run on Blackwell if the build supports the architecture. Confirm the compiler and toolkit. Physics and climate campaigns belong on GPU cloud for physics, climate, and CFD, not as a reason to insist on B200 by name. Rendering (frames from 3D scenes) is almost never why you rent this chip.
What to check before you rent
Name the product. B200 GPU, 8-GPU HGX/DGX node, or GB200 NVL72 rack are three different things. Ask memory per GPU, NVLink generation, cooling (air vs liquid), and CUDA driver version.
Blackwell is dense. Dense means more power and heat in a small space. A cloud that can boot one B200 may not be able to place eight in one server, or may preempt you. Spot (interruptible) capacity is a harsh place for a rare SKU you cannot replace at 2 a.m.
Egress is the fee for copying data out. Moving weights and checkpoints on and off Blackwell nodes is how the bill leaves the GPU line. Keep working files next to the chips.
GPU cloud partners (placeholder)
Partner rows below are placeholders until terms are signed. No live rates. No outbound URLs. When links go live, they will use rel="sponsored".
| Best for | GPU types | Notes |
|---|---|---|
| Partner TBD - 8-GPU B200 training nodes | NVIDIA B200 / HGX B200 | Placeholder. Confirm NVLink, memory per GPU, and when the reservation actually starts. rel="sponsored" when live. |
| Partner TBD - Blackwell inference | NVIDIA B200 with a serving stack you can run | Placeholder. Whole GPU, region, and FP8/FP4 support. rel="sponsored" when live. |
| Partner TBD - overflow while a cluster is sited | On-demand NVIDIA B200 | Placeholder. A meter that can hit zero. Not a substitute for powered land. rel="sponsored" when live. |
This table is not a ranking. It will reflect partner relationships once partners exist.
GPU cloud pricing varies. Verify live rates.
There is no honest single dollar-per-hour number on this page. Blackwell list prices move fast, and many public "from" figures are for a different product than the node you will get. Quoted rates often skip storage, data transfer, idle reservations, and liquid-cooling premiums. See the GPU cloud pricing index for how we talk about rates. We will not invent hourly prices here. Treat every public figure as stale until you re-check the provider.
Compare hours you will actually run, and whether those hours exist on the calendar you need. A cheaper Hopper GPU this week can beat a famous Blackwell GPU next month.
When GPU rental stops working
Rental stops working when utilization is high and predictable, you are standardizing on Blackwell, and the next constraint is megawatts and a site, not another waitlist. A megawatt is a large unit of electrical power. NVIDIA's own DGX B200 and GB200 NVL72 pages are describing factory-scale machines. Those machines need a floor with power and cooling, not a credit card.
The honest alternative is powered land: a development site with a credible path to large-load electricity. Browse the U.S. data center directory, then read when GPU clusters need powered land. Hybrid is normal. Rent B200s to prove the generation. Site the cluster that never turns off.
Find powered land when you need a site. Rent GPUs when you need capacity now.
Related
FAQ
Is B200 the same as GB200?
No. B200 is the Blackwell GPU. GB200 pairs Grace CPUs with Blackwell GPUs. GB200 NVL72 is a 72-GPU rack. Ask which of those three a provider is actually selling.
Do I need B200 if H100 or H200 still runs my job?
Usually no. Rent Blackwell when Hopper memory, throughput, or wait time is the real limiter, and when the software you run is ready. A working H100 cluster this week beats a B200 brochure.
Will my H100 training code run on B200?
Often yes if it is ordinary CUDA / PyTorch, but you still confirm drivers, toolkit version, and any FP4 or FP8 paths you want to use. Test a small run before you move the production job.
Why are B200 rentals hard to find?
They are a new, dense generation. Providers buy them in nodes and racks, not as loose notebook cards. If the quote is "available later," treat that as a different product from capacity now.
When is a dedicated Blackwell cluster cheaper than renting?
When the same shape would be busy most hours for a planning horizon in years, and you can design power and cooling around it. Count real hours. We do not publish dollar-per-hour rates. Use the pricing index, then re-check the provider.
What if the limiter is power and a site, not another B200?
Then rental is the wrong product. Use the powered-land GPU guide and what powered land is.
Sources
- NVIDIA DGX B200
- NVIDIA Blackwell architecture
- NVIDIA GB200 NVL72
- NVIDIA Blackwell platform announcement
- NVIDIA NVLink
- NVIDIA CUDA Toolkit
- What is powered land
- U.S. data center directory
- Powered Lands data center map
Need land or power instead? See the map or contact.